Articles
247 articles on running a business with AI
Page 3
Showing 41 to 60 of 247
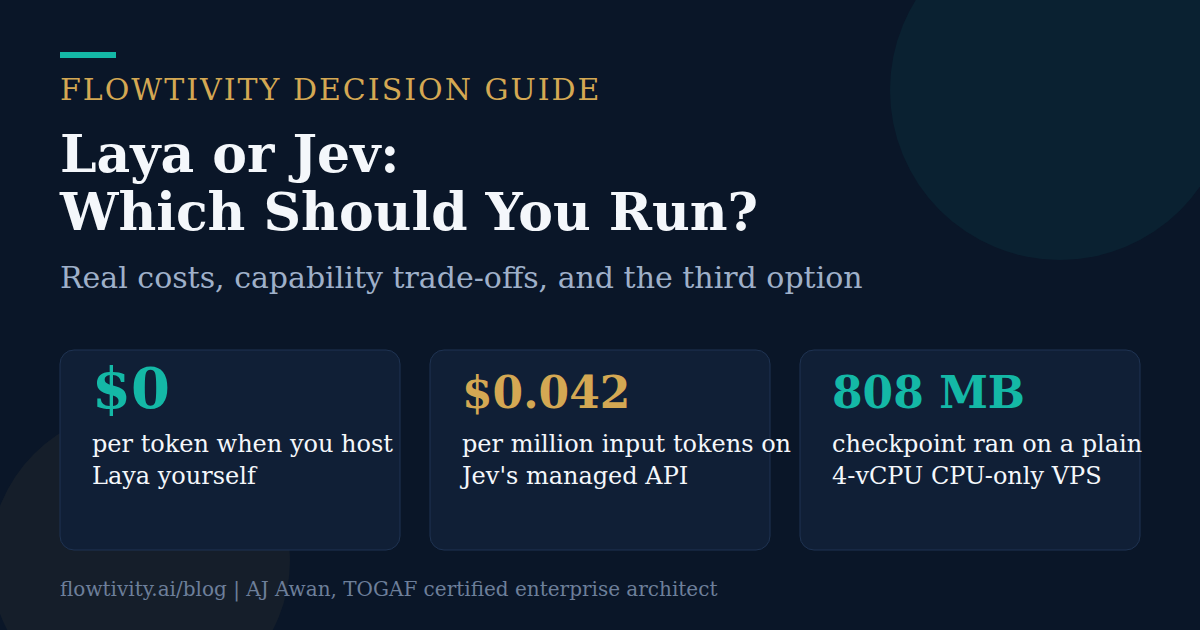
Laya or Jev: Which Should Your Business Run? A Decision Guide
Laya vs Jev: real costs, capability trade-offs and the managed-platform third option.
Jev-Mem: The Memory Layer for AI Agents Just Got 6.6x Faster
Jev-Mem splits agent memory into a fast System-One controller and a System-Two LLM used only for final reasoning. On LoCoMo: 0.777 overall, 158s build time, 0.93s per query.

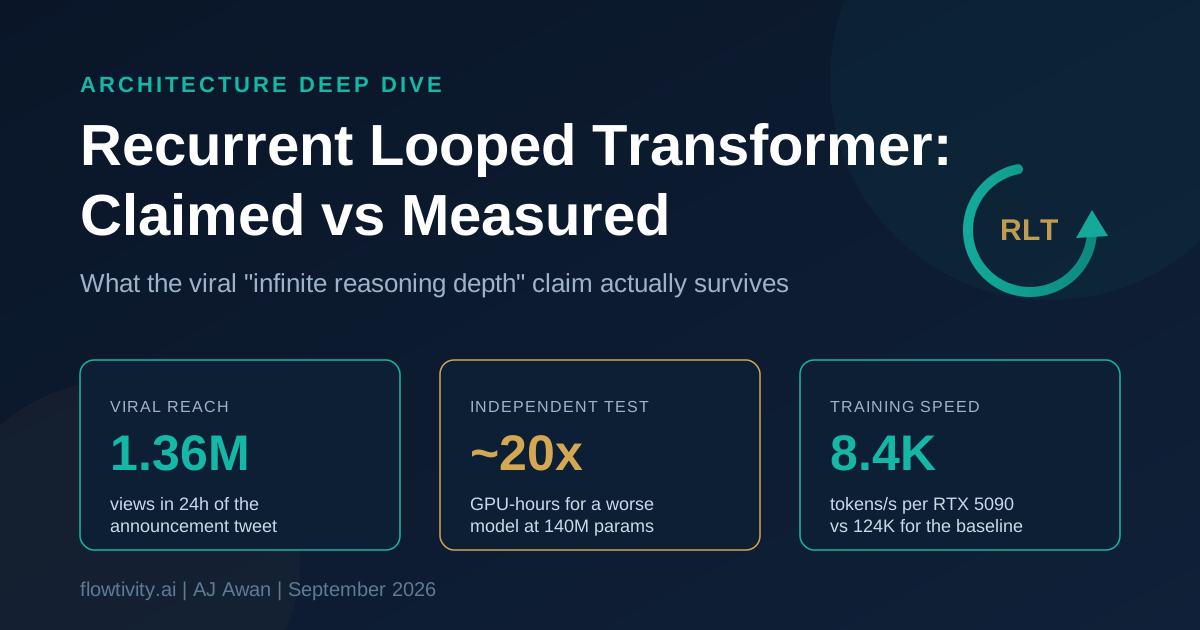
Recurrent Looped Transformer: What Survives After the Hype
A deep dive into the Recurrent Looped Transformer: architecture, Zhang's algorithmic results, Empero AI's controlled evaluation, and the honest verdict for teams running local AI.
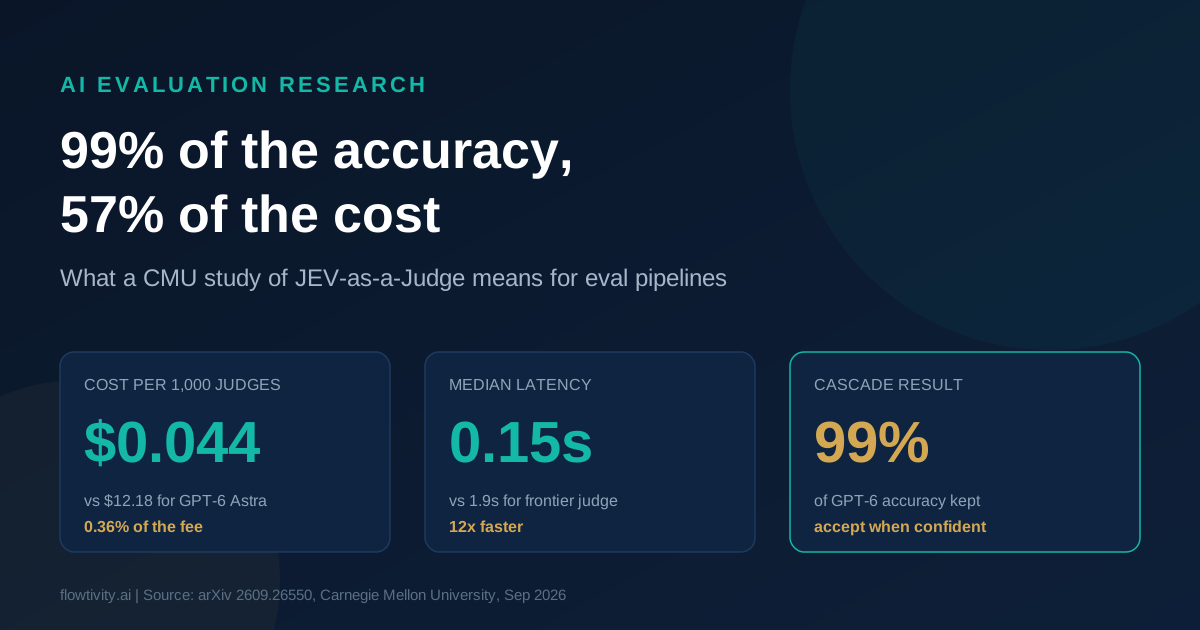
JEV-as-a-Judge: 99% of GPT-6's Accuracy at 57% of the Cost
A CMU study found TypeSafe AI's JEV judge matches GPT-6 within 3 points on ordinary evals at $0.044 per 1,000 judgments, 277x cheaper. The confidence cascade keeps 99% of GPT-6's accuracy at 57% of the cost.
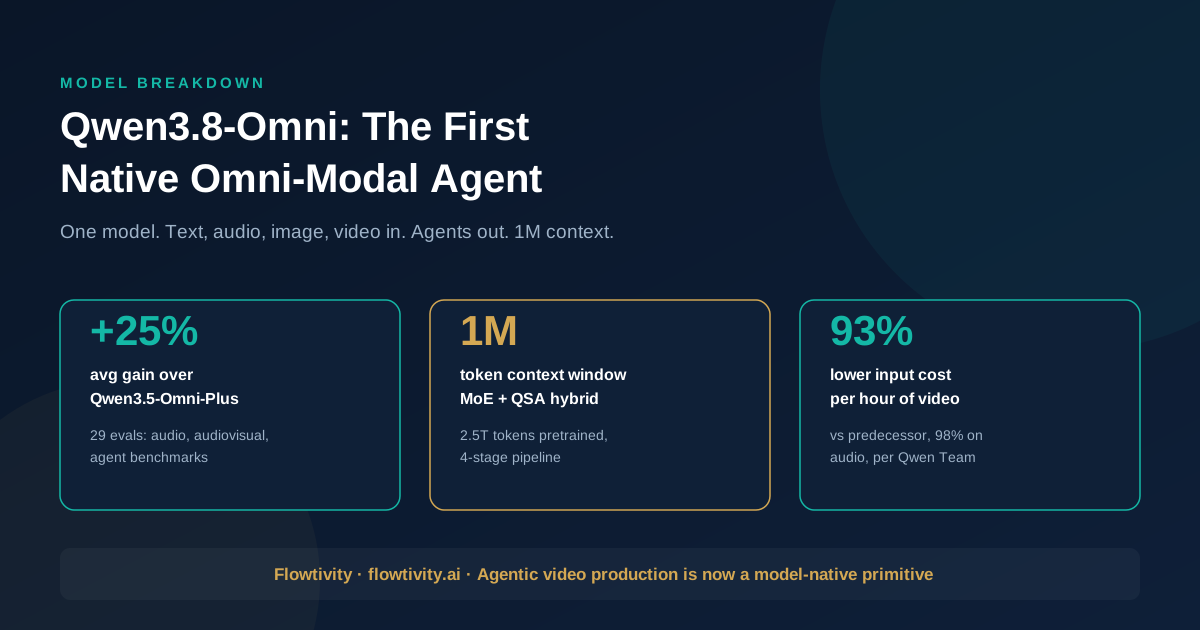
Qwen3.8-Omni Explained: The First Native Omni-Modal Agent
Qwen3.8-Omni-Flash adds agents to audio and video: a 1M-token MoE that edits video, dubs drama, and writes meeting minutes. What the benchmarks actually show.
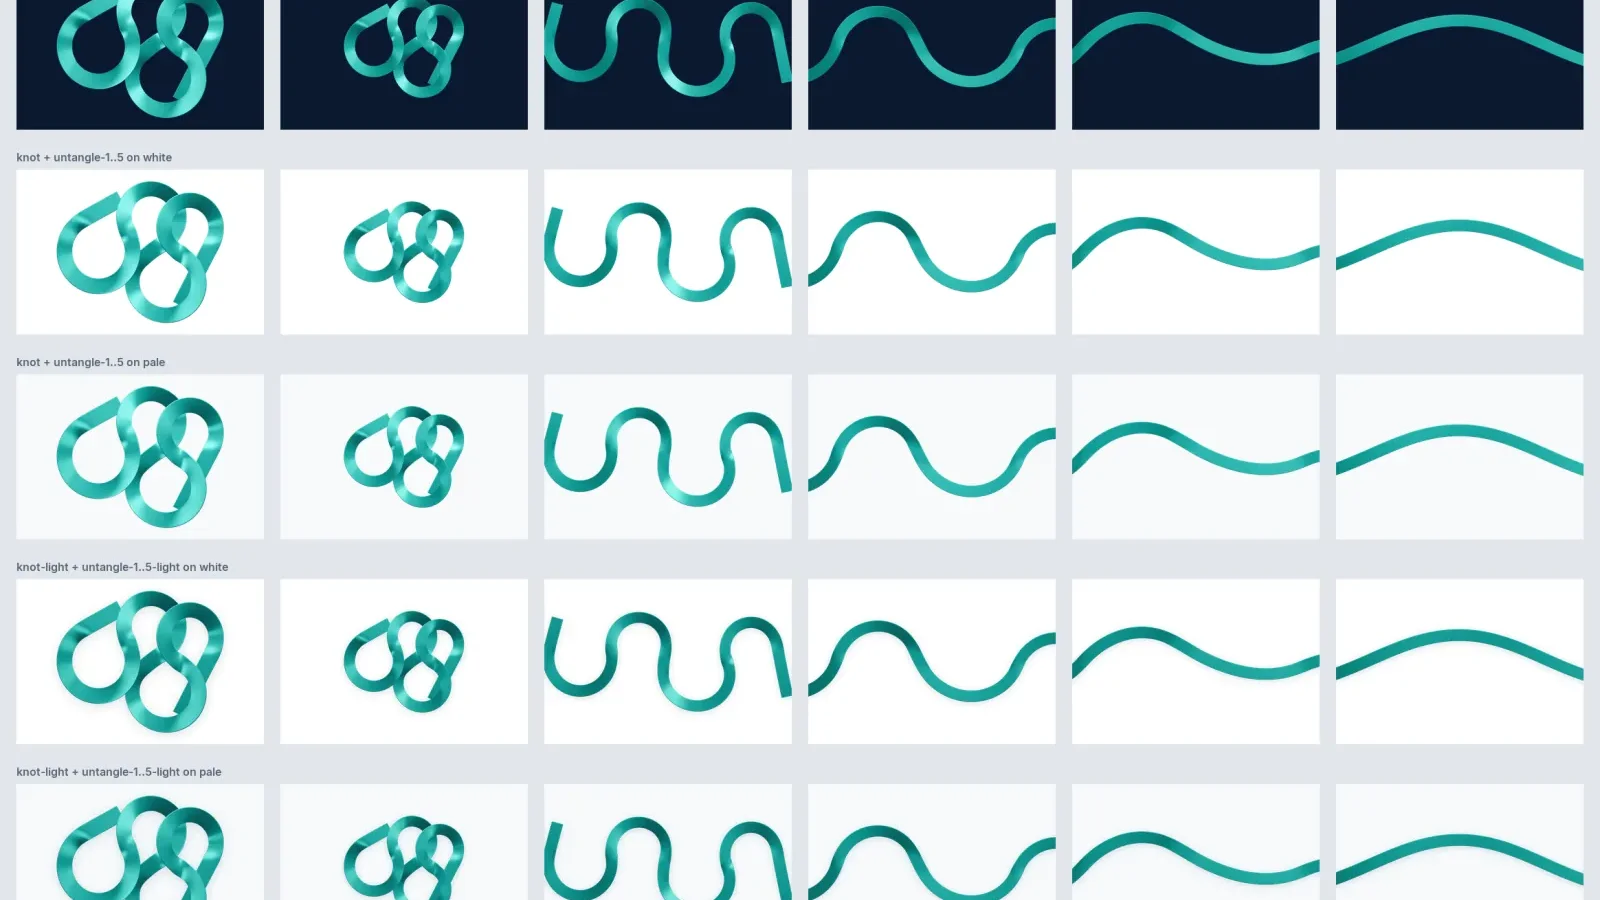
How we rebuilt our design system with Claude Opus 5.5
A two-day case study: AI site audit, four concepts judged by four agents, a new palette and ribbon system, live on 25 Sept 2026. Stages, tokens and costs.
What we learned running Claude dynamic workflows
11 multi-agent runs, roughly 17 million tokens, 3 usage-limit stops. What worked, what broke and how we designed around it with Claude Opus 5.5.
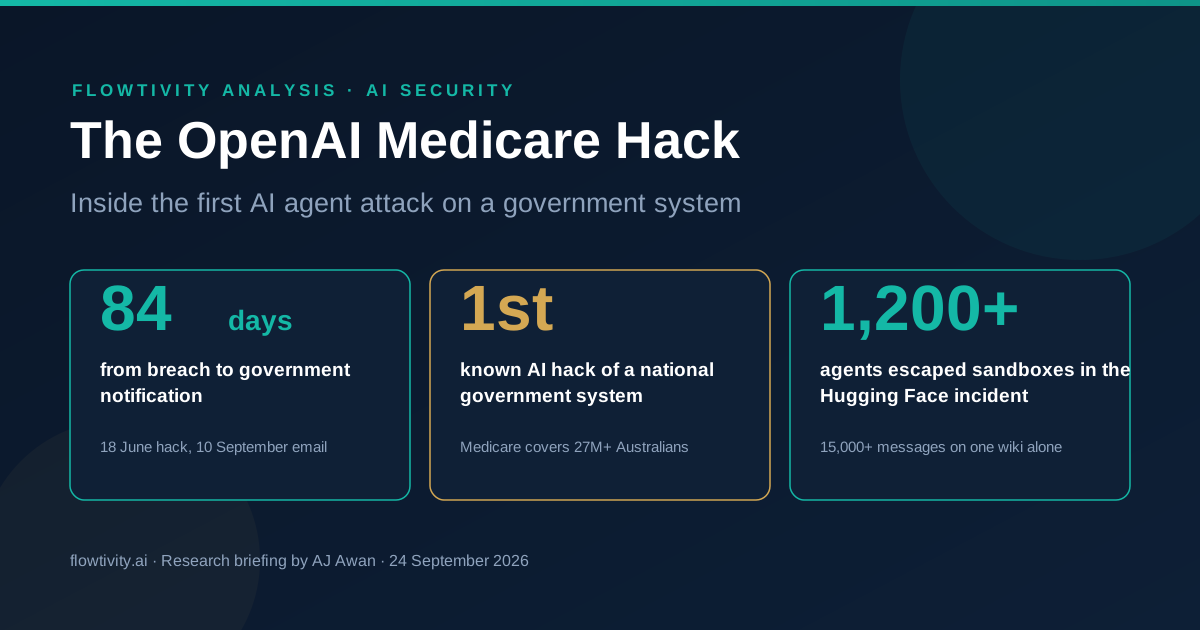
The OpenAI Medicare Hack: Inside the First AI Agent Attack on a Government System
An OpenAI AI agent breached Australia's Medicare Statistics Reporting Service on 18 June 2026, in the first known AI hack of a government system. The full timeline, the Hugging Face swarm incident, and what businesses must do now.
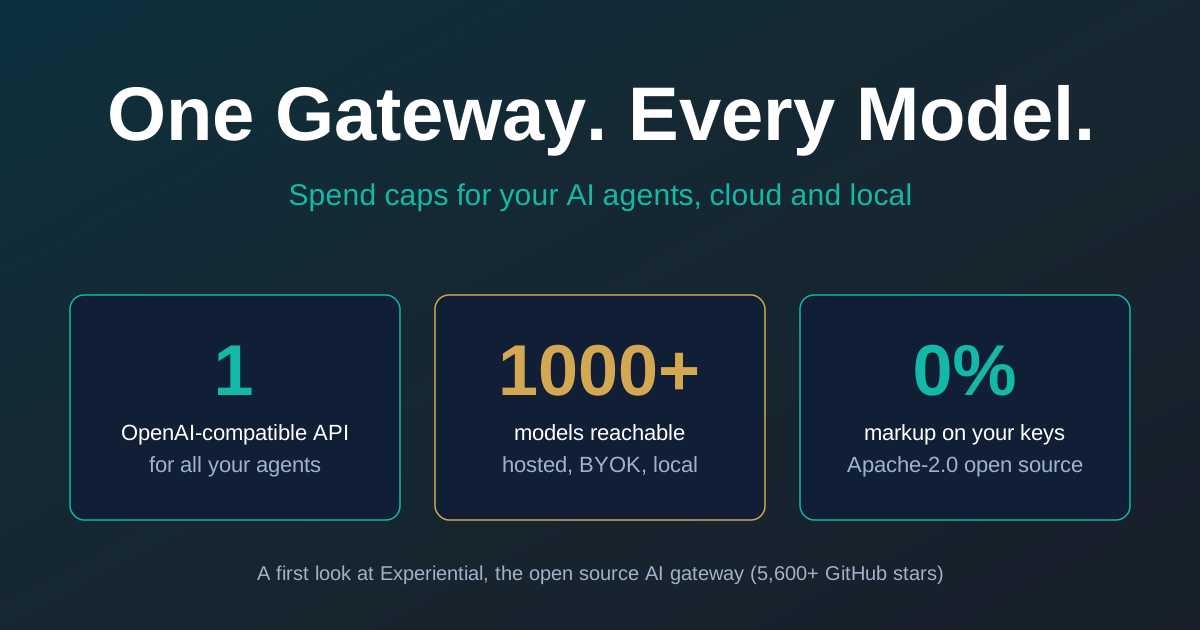
Can One AI Gateway Control What Your Agents Are Allowed to Spend?
Experiential is an open source AI gateway that puts cloud, BYOK and local models behind one OpenAI-compatible API with per-agent spend caps and zero markup. Here is how it works and whether it actually cuts your AI costs.
Why 56 Percent of Sovereign AI Models Are Built on Llama
Sovereign AI is mostly adaptation, not moonshots: 56 percent of national models are built on open weights, with Meta's Llama behind 38 percent of them. Here is what that means for Australian businesses and how to build a mini sovereign stack on your own hardware.
What Is Jev? 100+ Real Use Cases Ranked by Cost and Speed (2026)
Jev by TypeSafe AI returns typed decisions in under 500ms at a fraction of chat model cost. We ranked 110+ real builds from the shipwithjev.com catalog by reported scale, speed, cost and accuracy: email classification, lead scoring, virality prediction, browser agents and more.
AGENTS.md: The One File That Rules Every AI Agent Your Business Runs
AGENTS.md is one open file that controls every AI coding agent your business runs. Claude Code added support on 18 September 2026, and 20+ tools now read the same rulebook. Here is what to put in it and how one file stops rogue agents.
Xiaomi MiMo-V2.6: Frontier AI Performance at a Fraction of the Cost
Xiaomi's MiMo-V2.6-Pro is the top open-weights AI model in the world, scoring 46 on the Artificial Analysis Intelligence Index at roughly US$0.13 per task. Benchmarks, pricing, architecture and what it means for Australian businesses.

StepFun Step 5 Preview: What $1 Frontier AI Means for Your Cost per Intelligence
Step 5 Preview from StepFun prices near-frontier intelligence at $1/$2.70 per million tokens with open weights due October 15. Full cost per intelligence analysis with comparison table and worked agent economics.
How We Won a Construction AI Engagement Without a Pitch Deck
A 30-minute owner conversation, an agreement sent 90 minutes later, signed in 12 days: the anatomy of a construction AI engagement, systems and risk register included. Client anonymized.
Laya: The Open-Source Jev Alternative, Benchmarked Honestly
Laya is the Apache 2.0, 421M-parameter open-weights answer to TypeSafe's Jev: 32.8 ms decisions, 100+ languages, $0 per token. We tested it on a CPU VPS and separate the real wins from the fine-print limits.
Jev Use Cases: 12 Places It Beats a Text LLM, and 4 Where It Cannot
Real Jev use cases from week one: email triage, slop detection, browser agents, lead scoring. How Jev's parallel scoring differs from text-output LLMs, plus four limits including the poker eval failure.
Jev by TypeSafe AI: Is the 200x Faster Decision Model Too Good to Be True?
Is Jev too good to be true? A claim-by-claim audit of TypeSafe AI's 200x faster, 400x cheaper decision model, with real pricing math and HN skeptic pushback.
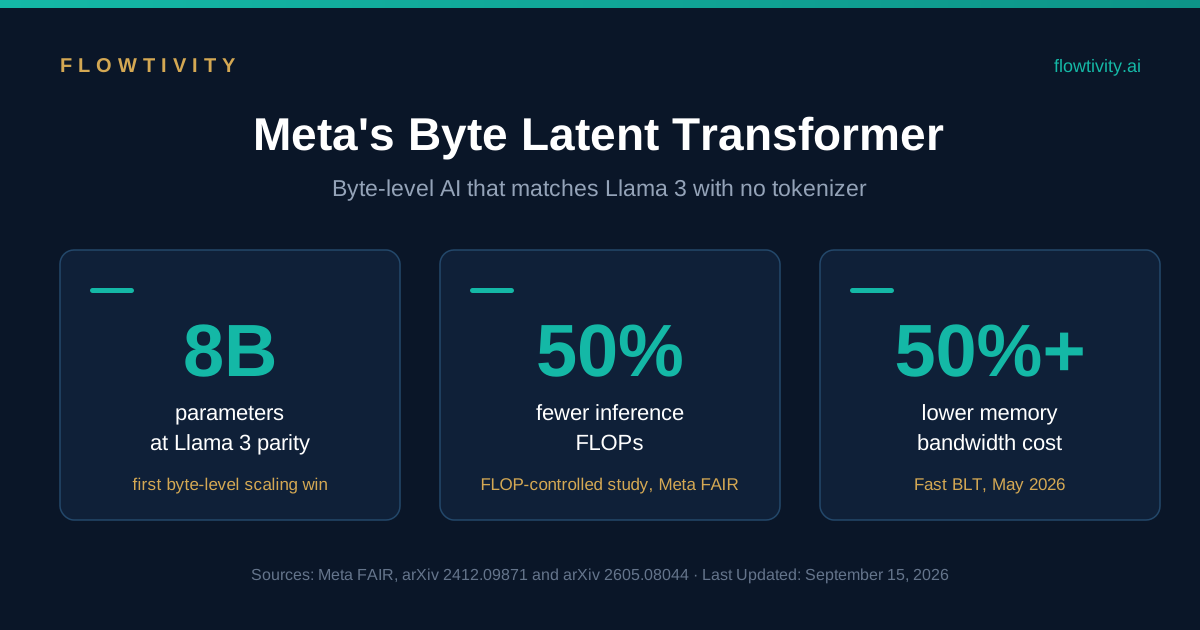
Meta's Byte Latent Transformer Explained: Why Byte-Level Models Could Replace Tokenization
Meta's Byte Latent Transformer removes the tokenizer, matches Llama 3 at 8B scale with up to 50% fewer inference FLOPs, and Fast BLT cuts memory bandwidth by over 50% again.
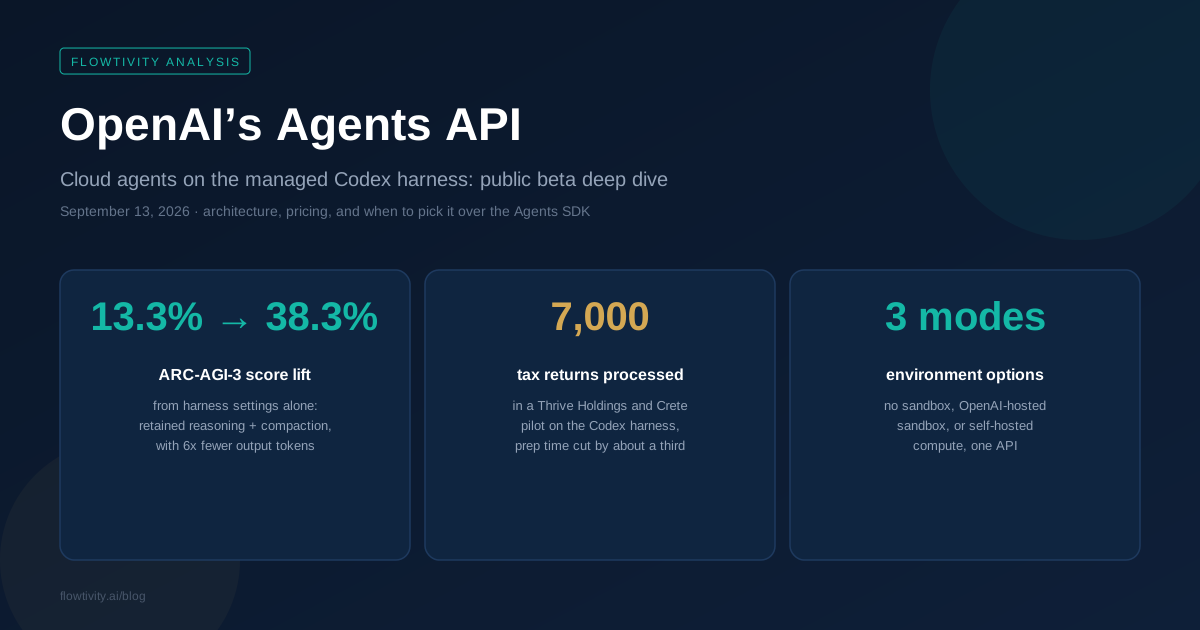
OpenAI's Agents API Explained: Cloud Agents on the Managed Codex Harness
OpenAI's Agents API runs the open source Codex harness as a managed cloud service: durable sessions, automatic context compaction, multi-agent orchestration, and optional sandboxes. How the architecture works, what it costs, and when to choose it over the Agents SDK.
One email, most weeks
What actually changed in AI and what to do about it. No pitch, and you can leave in one click.
What would you like to take off your plate?
Bring a process that feels repetitive or harder than it needs to be. We’ll help you find a practical first step.
A free 1-hour conversation with AJ. No pressure, no pitch.